reposource-backed
Jev Search
Jev chooses sources and query settings, then re-ranks results returned by search engines. It does not generate an answer.
MANY ITEMS, FEW DECISIONS
Thousands of pages, mentions, emails, ads or candidates screened by parallel yes/no and score questions before anything expensive runs.
Choose a project, read its requirements, then follow its setup reference or a related guide.
Node.js 22.12+, pnpm 10.8.0 and a Cloudflare login
Python environment with pip; a folder of Markdown notes
Python 3.12+ and pip
Score a small shortlist of passages, preserve their source IDs and pass selected evidence to your answering model.
Re-rankers, relevance gates and retrieval fusions with per-item costs from each author.
Jev chooses sources and query settings, then re-ranks results returned by search engines. It does not generate an answer.
Hundreds of pages are screened for internal-link fit through thousands of yes/no decisions.
A pipeline ranks social mentions by intent, fit, competitor context and reach.
One profile is scored for fit, chance, confidence and mismatches across 400 companies.
Business ideas around quotes, leads, support, clipping, applications, marketplaces and browser agents.
Parallel judgments score advertising creative against a fixed rubric.
Jev classifies and scores a creator's own posting history across several criteria.
A visual comparison places Jev next to Luna, Sonnet and Flash on email classification.
A PostgreSQL extension that exposes Jev-backed categorical judgments over table rows.
Two PyPI packages: a `JevRerank` postprocessor using Score and single/multi selectors using Choice for LlamaIndex routing.
Outgoing relationships become choices, Jev returns next-hop probabilities, and a beam search walks the graph; shipped as a library, notebooks and a Streamlit app on Neo4j's public Companies knowledge graph.
Jev scores file and folder names so an ensemble of walkers is allocated across the most probable paths; a Bun CLI with recursive and multi-walker modes and JSON traces.
A DuckDB extension that calls Jev to classify rows of any CSV, Parquet file or table from SQL.
A video demo classifying 500 emails in seconds.
An early video demo running Jev over 1,500 of the author's own emails.
A UK events platform compared three models on approving or rejecting 50 real listings (venue hire, products and cancelled events filtered out), publishing the cases as a PDF.
An early-access test in which the author had Jev score his own writing corpus; widely cited by other write-ups as the first non-TypeSafe measurement.
A team pointed Jev at a private benchmark and reports it came within a few recall points of their fine-tuned Qwen at matched precision, while the fine-tune remains faster and has not been replaced.
A playable demo that runs 16 typed judgments on your text (tone, urgency, AI-written detection and more) on every keystroke with a single API call.
A pre-alpha PostgreSQL C extension exposing typesafe_noul(), typesafe_classify(), typesafe_score() and batched variants that call the API from SQL.
A DuckDB extension with jev_choice(), jev_score(), jev_noul() and jev_ask() returning real SQL types, batching 16 rows per request and caching identical queries.
A Mac app routes setup and troubleshooting questions to the right built-in manual article with Jev when no local model is loaded, showing real docs instead of generated text.
Near-real-time scoring of TikTok and Instagram hooks against roughly a hundred synthetic personas with Jev.
Seven independent writing checks (hedging, filler, passive voice and more), each returning its own verdict, confidence and the driving sentence; runs simulated without a key.
A free yes / no / maybe oracle that calls jev-latest through the System One API with live search for current facts; no account needed.
Evaluates Jev reranking against bge-m3 embedding search over an Agent Skills Hub catalog, with judge-bias and robustness analysis.
Adds `jev()` semantic predicates to plain Postgres through a CLI, HTTP and SDKs, with a SQLite cache and an `--explain` cost preview; a playground is hosted.
A Jev-driven recruiting agent with a local web UI that shows evidence quotes behind each decision; a short demo video is linked.
Load a Telegram JSON export and Jev labels each post's type, quality, sentiment and reaction tone; runs through Vercel AI Gateway or a TypeSafe key, with label export.
Upload a research-paper PDF; text is extracted in the browser, split into roughly 1,000-word passages, and a fixed set of small questions is asked per passage in parallel, then combined into weighted scores.
A pull request on the TrainLCD Functions repository adds Jev-based re-ranking of suggested stations and measured spikes; the author says Jev is also going into part of the app's AI chat.
A Python package for Jev-powered relevance filtering and reranking, with a Hugging Face blog walkthrough covering the API, filtering and evaluation results.
The ielab document-ranking toolkit gained a jev module, with code that uses TREC human relevance judgments to test whether Jev's probabilities are actually calibrated.
Browse YouTube transcripts by meaning with Jev analysis, subtitle export and a Vercel setup guide; Turkish UI.
'jev, find me stuff in my system' — a file finder that asks Jev which files match a natural-language request.
Countable rules plus one judgment model: ten yes/no questions per paragraph flag AI-writing tells. Zero dependencies.
A hosted detector that scans text for AI-written 'slop' using Jev decisions rather than a generative model.
An OSS library from the LlamaIndex founder: give a document plus natural-language category rules and Jev predicts the category (classify) or the boundaries between sub-documents (split). OCR backends: liteparse (fast, free) or LlamaParse for complex layouts.
A high-throughput sifter for synthetic and pretraining datasets: stream Parquet and JSONL, filter and score every row with Jev.
Transcript in, topic in, clips out: Jev picks the segments of a 90-minute video for any topic in under two seconds.
Type 'Urgency' at the top of a column and, as you type, Jev works out you want each row rated from 'no follow-up needed' to 'urgent' — spreadsheets that recalculate meaning, not numbers.
A native DuckDB extension for Jev classification, scoring and semantic predicates from SQL: vectorized input, batching, bounded concurrency, dedup and cross-query TTL/LRU caching. Distinct from colliber/duckdb-jev.
Picks the most likely command from the last 100 unique history entries and ghosts it after the cursor, fish-style, using Jev to rank by intent.
Wraps commands and uses Jev to match mistyped subcommands by intent, not edit distance: `git record` → `git commit`, `npm add` → `npm install`.
An inspectable comparison of Jev Noul and Qwen3-Reranker-0.6B on retrieval ranking tasks, with the harness and raw model responses published.
A Cloud Run remote function lets BigQuery call Jev to classify support tickets and expose the resulting judgments to SQL queries.
A Telegram moderation bot that uses Jev for optional text, bio, advertising and language judgments. Image moderation runs through a separate local detector.
Classifies Gmail threads into workflow labels with Jev and can optionally remove them from the inbox. The tool does not send mail.
A Chrome extension that applies BAIT, CORP and BRAG labels to LinkedIn posts using Jev, with a local server for the API key and heuristics to reduce calls.
A workflow for uploading, screening, training and evaluating datasets, with Jev API calls used for the screening stage.
An open-source Mac tool for App Store Optimization with keyword analysis and listing workflows that the author connects to Jev.
CodeNib uses Jev to rerank code-search results and publishes integration docs plus an evaluation on 100 CodeNib Base issues.
A Chrome extension scores Hacker News stories on five factors with Jev and reorders the page using adjustable weights.
A Java System One client plus Spring AI modules for Jev judging, guardrails, retrieval filtering and reranking, and tool selection.
A CLI that uses Jev to judge relevance across repository folders, files and declarations, returning file leads and verbatim source excerpts to a coding agent.
A video demonstration of semantic search over a collection of Y Combinator startups using Jev decisions.
A live people-search workflow in which Jev screens candidate companies against an ideal-customer profile before treg finds and verifies contacts.
A Python command-line tool uses Jev to find relevant lines in selected local documents and knowledge-base text alongside lexical search.
A TypeScript CLI and local MCP server ask Jev to rank source fragments and return exact excerpts with paths and line numbers to coding agents.
A Rust code-search CLI first scores source paths with Jev, then ranks overlapping windows from the selected files and prints matching snippets.
A Pi extension exposes Jev ranking, classification, local snippet retrieval and general typed evaluation while retaining the normal coding model.
A standalone Rust binary searches a codebase using natural-language questions and returns relevant files and line ranges with scoring details.
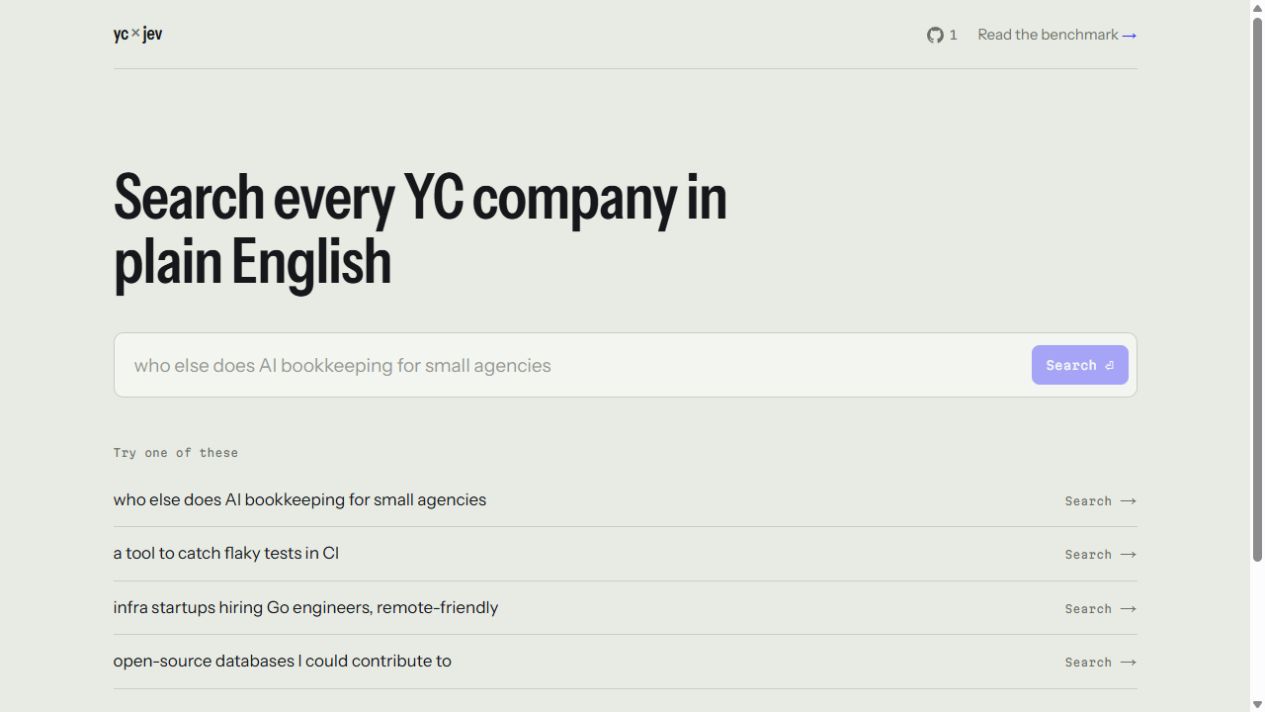
An independent reranking benchmark paired with a live natural-language search over Y Combinator companies. The app uses Jev for query routing and reranking after keyword and embedding retrieval.
A CLI, MCP server and library combine ripgrep recall with Jev judgments over candidate files and passages. Results contain original source excerpts with paths, line numbers and explicit omitted ranges.
A Python code-navigation library builds a structural index and composes small Jev judgments into best-first source searches. Its commands can trace known workflows or find matching functions while saving source provenance and partial results.
A local semantic engine answers typed questions about application state and documents using an NLI model. It adds evidence retrieval and a Relation primitive alongside a Python API and TypeSafe-compatible HTTP server.
A local Rust search tool combines keyword discovery with Jev ranking and delivers source excerpts through a CLI or MCP. Its setup command connects Codex, Claude Code and OpenCode and can supply retrieval context when a code question is submitted.
A Rust CLI searches source trees and text documents with local BM25 recall, then uses Jev to filter and order candidate files. Results carry paths, line ranges and relevance scores in a grep-style interface.
A Python CLI parses source files into functions and asks Jev the same yes/no question about each unit. It ranks the returned probabilities and uses chunks when a language cannot be parsed at function level.
A retrieval study compares typed Jev scoring strategies with dedicated rerankers and open-model controls on the same passage candidates. Saved provider responses, query-level evidence, bootstrap intervals and an interactive viewer support inspecting each result.
A spatial reference explorer retrieves images and archive clips from source-linked collections. In the local app, Jev selects bounded search phrases and highlights image references from their metadata; collected references can be pinned and exported.
GPT Researcher can use Jev to score scraped passages for usefulness to a research question. Its compressor selects context from the same chunk pool and output budget used by the alternative retrieval pipeline.
MemSearch includes an optional Jev reranker for project-memory passages. Candidate excerpts are scored against the query before the application chooses which memories to return.
ThoughtDAG searches local agent sessions and visual conversation canvases. Its optional Jev layer helps select relevant excerpts and topics before the chosen language model develops an answer.
A local SQLite memory system exposes retrieval through MCP and can rerank a candidate pool with Jev. Its implementation uses Noul relevance judgments before returning selected memories.
Needle uses Jev to rank passages and select the strongest source sentence for a natural-language query. Its Chrome extension highlights those sentences on the original webpage, and a React interface also accepts pasted text.
A desktop office suite indexes local document text in SQLite and can use Jev to reorder search results. The optional reranker evaluates candidate files against the search question before showing the ranked list.
XERJ can send retrieved documents to Jev for query-relevance judgments and reorder the result list. Its search implementation keeps the decision step separate from ordinary retrieval scores.
Pi MCP Adapter can rank MCP tools by meaning using a System One evaluator. Project policy specifies which servers may share data for semantic search, alongside the existing word and regex search modes.