Every public measurement of Jev found so far: TypeSafe's evals dashboard, independent benchmark repositories, and vendor and builder tests on their own data.
Independent runs and vendor tests side by side; each entry quotes its own sample, task and baseline.
The public dashboard behind the launch numbers: four workflows (security incidents, agent-trace observability, invoice processing, customer service) and ten model configurations compared on accuracy, cost and latency.
A framework comparing hosted Jev with a local GLiNER2.5 on zero-shot single-label classification (AG News, Banking77, DAIR Emotion) for accuracy, calibration, selective-automation coverage and latency, with bootstrap intervals.
A UK events platform compared three models on approving or rejecting 50 real listings (venue hire, products and cancelled events filtered out), publishing the cases as a PDF.
A team pointed Jev at a private benchmark and reports it came within a few recall points of their fine-tuned Qwen at matched precision, while the fine-tune remains faster and has not been replaced.
Argues the headline multipliers are real but chosen against the slowest and priciest baselines; against TypeSafe's own intelligence peer the gains shrink.
A roundup that notes the 193.6x / 444.6x come from workflow evals whose reference answers are other models' outputs, while the demo latency comparison is a different workload.
A mini-site (What Shipped / The Evals / The Guarantee / Prior Art) concluding that pricing is verified, "can't hallucinate" is schema-only, and the multiples hold only against frontier reasoning models on TypeSafe's workflows.
An official docs page listing failure modes of jev-1.13 with workarounds: literal reading of implied conditions and negations, unreliable arithmetic and counting, dates treated as text, weak multi-hop indirection, degradation with irrelevant state, prompt-injection vulnerability, and inconsistent invariants between related questions.
A bilingual (Traditional Chinese / English) evidence map of where Jev holds up and where it breaks, with API-call receipts under suites/. Its thesis: success tracks whether the answer is derivable from the supplied state rather than from outside knowledge.
A thread benchmarking Jev on public prompt-injection data, thresholding calibrated probabilities in code, with a dashboard and calibration analysis in follow-ups.
HiringCafe (2.5M monthly active users) scores resume-to-job-description relevance; the founder ran Jev against a human-labelled set and compared Spearman correlation and cost with three other models.
LangChain tested Jev against LLM judges on accuracy, repeatability, latency and cost to see whether System One models offer a new approach to online agent evaluation; evaluator code in the repository.
An open-source CLI that builds calibrated classifiers from human feedback on top of Jev, using GEPA prompt optimisation — because a foundation model still needs aligning to your own criteria.
An LLM gateway that mimics TypeSafe's structured output so local models can be scored against Jev; Needle 3 on an M4 Pro came out worse than Jev, Qwen3.8 27B and OSS 120B.
The ielab document-ranking toolkit gained a jev module, with code that uses TREC human relevance judgments to test whether Jev's probabilities are actually calibrated.
A Chinese-language learning repository with five runnable Python demos and the author's Jev 1.13.0 experiments on question fan-out and decision boundaries.
A CLI that uses Jev to judge relevance across repository folders, files and declarations, returning file leads and verbatim source excerpts to a coding agent.
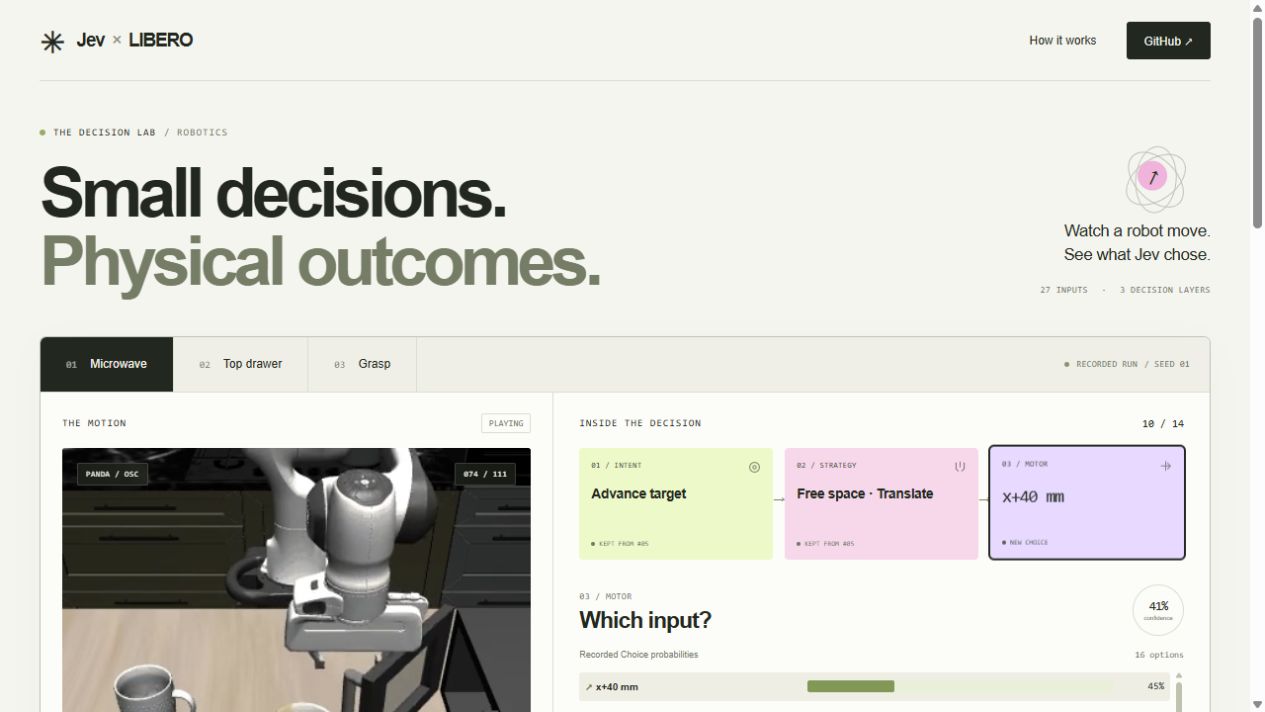
A configurable LIBERO robot-control experiment that combines Jev decisions with reversible physics previews. An interactive replay follows intent, motion family and control choices alongside saved trajectories.
A local TypeScript library and CLI where Jev chooses exploratory browser actions and assesses observed results. Playwright executes configured actions, exact assertions decide outcomes, and saved traces support replay.
A browser and macOS computer-use harness that checks completion claims against observed state and gates irreversible actions with Jev. Its dual mode also delegates mechanical steps to Jev while a driver handles broader decisions.
An independent Jev-style project that freezes a language-model backbone and trains a small decision head over cached candidate features. It publishes typed probability outputs, datasets and browser presentations of its benchmark and game policies.
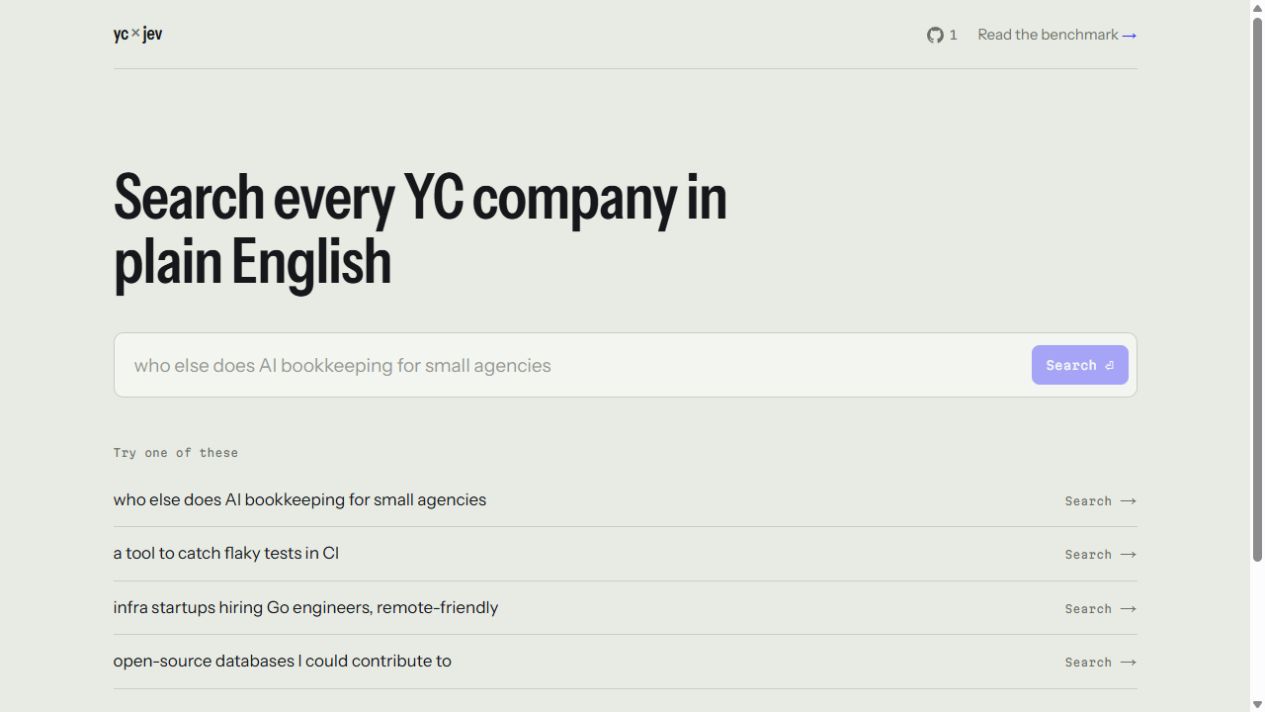
An independent reranking benchmark paired with a live natural-language search over Y Combinator companies. The app uses Jev for query routing and reranking after keyword and embedding retrieval.
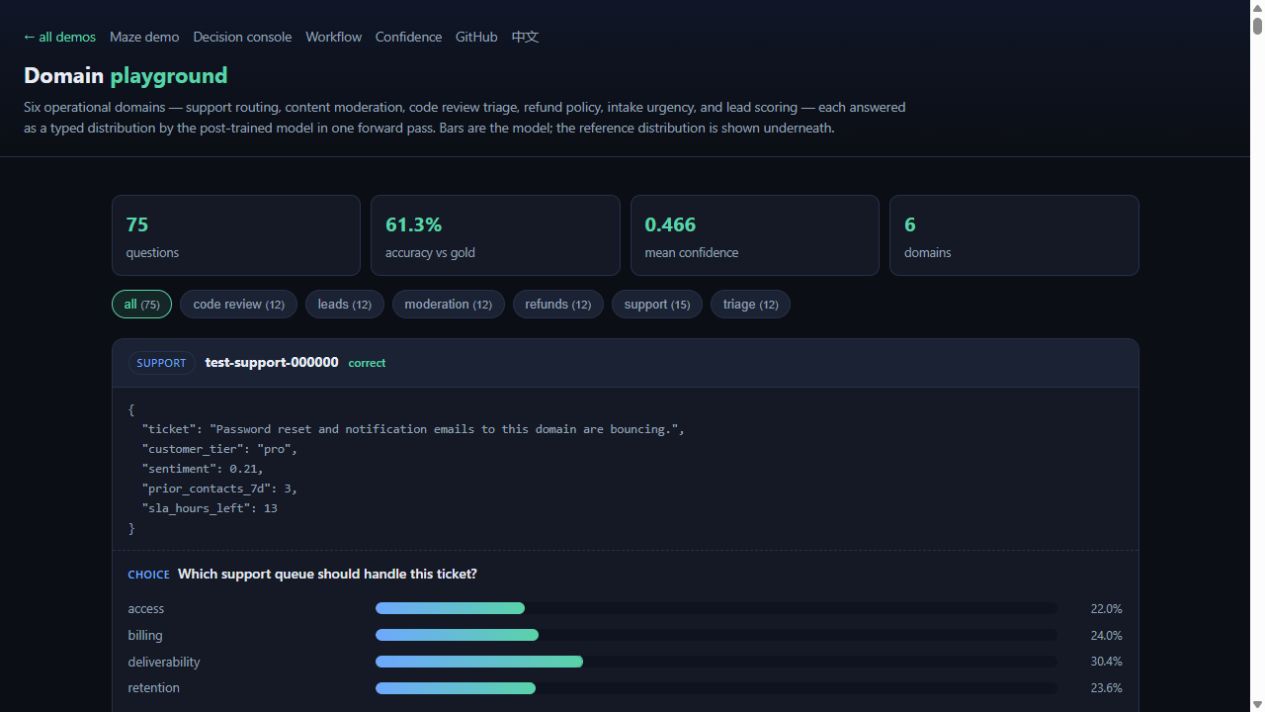
An independent evaluation site and data repository for Jev and LLMs answering the same typed questions. Public boards link accuracy, calibration, costs and latency to human-labelled tasks and individual decision logs.
A Playwright reporter asks Jev which discovered browser tests are relevant to a code change before browser execution. It combines changed paths and patches with test metadata and optionally test source.
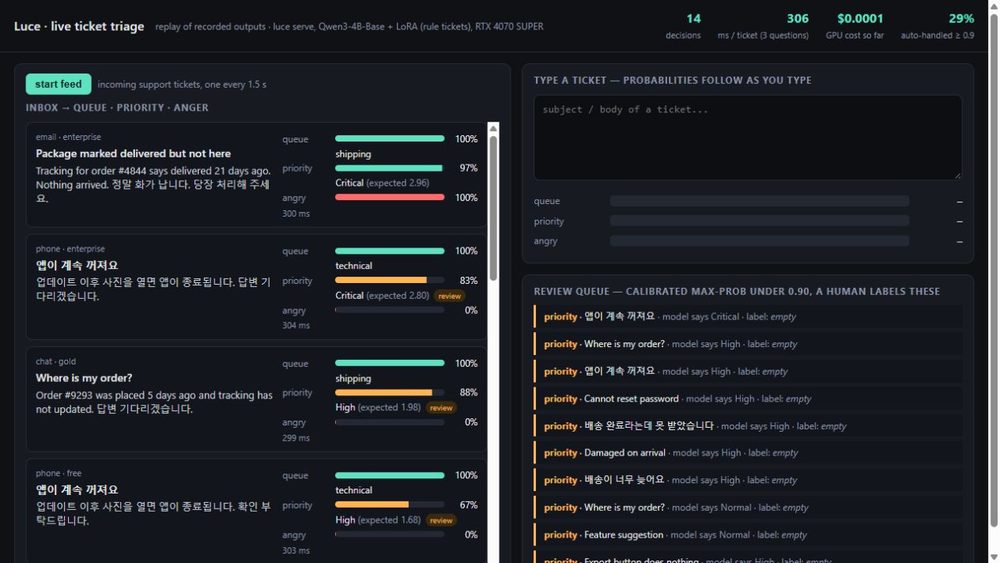
A task-specific pipeline generates or labels data with an LLM teacher, trains a LoRA and decision head, then evaluates and serves Choice, Score and Noul probabilities. A public support-triage replay shows saved model outputs and review routing.
An end-to-end research toolkit builds decision records, trains and calibrates candidate scorers, and serves a Jev-compatible API. Its released Qwen3.5-0.8B model ranks supplied web actions, while the public demo presents recorded Mind2Web decisions.
An independent family of LoRA adapters and scalar decision heads returns Choice, Noul and Score outputs over pinned Qwen backbones. The project publishes training data, evaluation records, a CPU classification workbench and interactive saved-decision replays.
A Qwen3.5-4B LoRA adapter answers multiple typed questions without generating answer tokens. Its runtime combines label-token readout with a learned candidate head, option-order averaging and saved calibration profiles.
A local NLI backend scores caller-defined Choice, Score and Noul questions, with temperature scaling and low-confidence abstention. Python, CLI and MCP interfaces expose the same decision layer.
A benchmark compares Jev and other typed decision systems using frozen tasks, explicit adapters and published result artifacts. Its score views combine capability, calibration, latency and estimated cost, with public and sealed evaluation material.
A CLI evaluates Jev against labelled application data, chooses per-question thresholds on one split and checks them on held-out examples. It writes a threshold lock and report, supports low-confidence fallback, and fails CI when accepted accuracy or coverage drifts.
A preregistered audit compares English and Spanish state and instruction combinations for Jev on paired human-labelled datasets. The repository publishes the runner, frozen prompts, response-derived results and a CLI for repeating the protocol on other labelled data.
A deterministic restaurant simulator that replays the same seeded dinner under rule-based, camera-assisted and Jev-planned service. Servers choose from feasible task tours, and the app logs the observations, candidates, confidence, latency and resulting service metrics.
An independent evaluation of pinned jev-1.13.0 across classification, routing, inference, moderation, legal clauses and rubric scoring. The paper uses frozen task templates, reports calibration and selective prediction, and releases its harness and raw model responses.
A training-free algorithm that recovers numerical outputs by recursively narrowing a range through a multiway tree of Jev-like choices. The paper preserves the original question in context and studies how range selection differs from direct candidate selection.
Distilled Qwen models answer Choice, Noul and Score questions by reading option-token logits. The project releases 4B and 9B weights, fitted temperatures, a TypeSafe-compatible server and runtimes for CUDA or GGUF.
A training and deployment library adapts language-model backbones to typed decisions with learned pointer heads or direct option-token readouts. It publishes LoRA checkpoints, data preparation, calibration and evaluation tools alongside an archived application replay gallery.
A family of open 4B and 27B models applies stated rules and policies through typed option probabilities. The repository includes data generation, distillation, quantization, evaluation and a TypeSafe-compatible server, with GPU and Apple Silicon builds.
An evaluation library expresses agent, quality and security checks as typed questions and packs compatible checks into shared decision requests. The same definitions can measure recorded traces or gate an agent step, using hosted Jev or supported local decision engines.
An offline linter checks Jev request design before inference, including missing escape options, broken state references and malformed criteria. An optional semantic layer asks Jev whether a structurally valid question has missing or ambiguous answer boundaries.
An independent CUDA runtime scores verified single-token option labels with existing language-model weights. It batches independent fields through vLLM, reuses shared prefixes when supported and assembles typed output in code; browser experiments also use local WebGPU models.
A frozen-protocol study checks Jev's option probabilities and output schema on Banking77 and CLINC150. It publishes corpus pins, raw responses, scoring rules, amendments, controls and a separate blind rescore.
A reproducible zero-shot evaluation freezes the LexGLUE test splits and maps legal classification tasks to Choice or per-label Noul questions. Its runner saves completed requests, checks model-version changes and writes micro/macro-F1, calibration, usage and cost reports.
A retrieval study compares typed Jev scoring strategies with dedicated rerankers and open-model controls on the same passage candidates. Saved provider responses, query-level evidence, bootstrap intervals and an interactive viewer support inspecting each result.
A measurement harness compares many typed questions in one Jev request with the same questions asked separately. It varies state size and question count, repeats requests to estimate noise and publishes response-level usage, billing and latency evidence.
A local workbench runs open decision engines side by side and can compare them with hosted Jev. It includes a visual request builder, dataset benchmarks, truncation diagnostics and resource or concurrency measurements with separate engine processes.
An independent experiment compares Jev's reported probabilities with known uncertainty on fair dice, coins and option sets. It also tests whether typed decisions preserve probabilities stated in forecast documents, publishing recorded outputs and offline analysis scripts.
A MuJoCo robot workbench compares bounded skills, incremental movement and hierarchical control on manipulation tasks. It exposes decision traces, physical checks and alternative providers, including Jev, compatible chat models and a local MiniCPM model.
A Franka Panda simulator separates Jev's choice of manipulation intent from its choice of movement and gripper commands. A local executor applies those commands, and independent physical checks determine whether a task succeeded.
DeepEval offers Jev-based evaluation metrics and a TypeSafe model configuration. Custom evaluation criteria are converted into structured judgments for individual responses and conversations.
Opik instruments synchronous and asynchronous TypeSafe SDK clients. Evaluation states, questions, returned answers and usage can be captured in application traces.
A mathematics-to-animation pipeline uses Jev to review checkpoints while a separate authoring model develops explanations and Manim scenes. Typed questions assess evidence, blocking defects and the proposed repair target.